Campaigns
GPT Image 2.6 Flare vs Sunburst: Design a Fair Product-Ad Comparison
Product-ad workflow: OpenAI positions GPT Image 2.6 Flare for fast iteration and Sunburst for detailed visual work. That helps define test hypotheses; it does not establish which model will produce an acceptable product ad for your exact reference, wording and budget.
Make it with Panelly
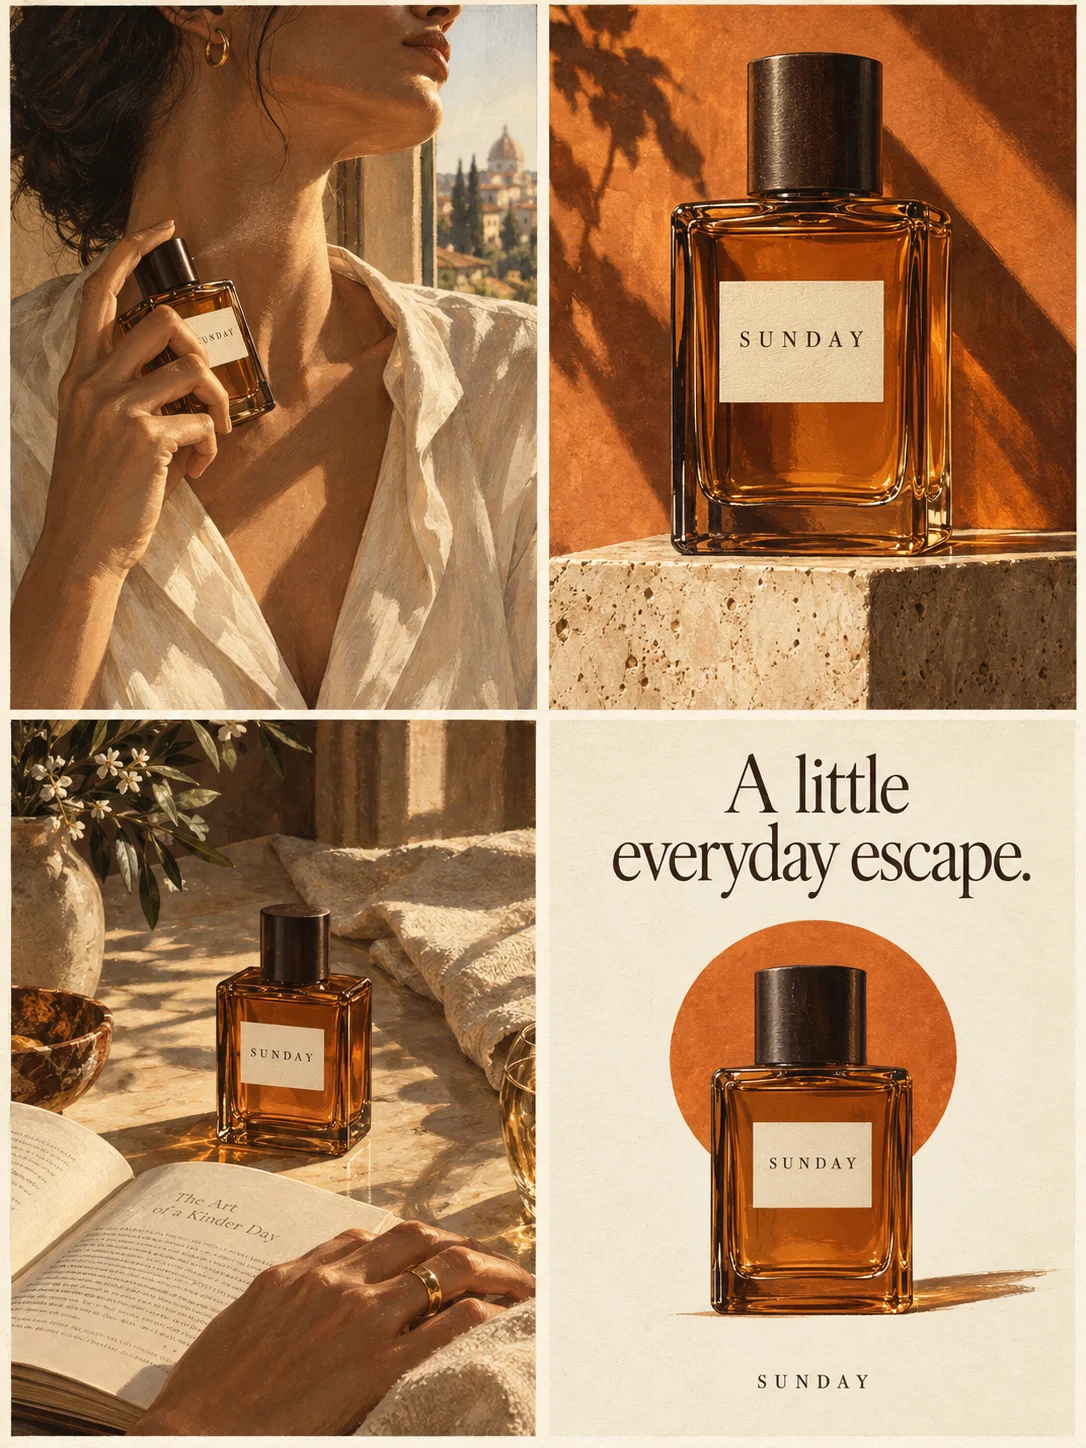
Four-panel product ads
Turn a product benefit into a connected four-panel ad. Explore a visual direction, refine the result through conversation, and download the complete image.
Try this in Panelly Edit the brief before you generate.
OpenAI positions GPT Image 2.6 Flare for fast iteration and Sunburst for detailed visual work. That helps define test hypotheses; it does not establish which model will produce an acceptable product ad for your exact reference, wording and budget.
This article gives a comparison plan, not benchmark results. No model call, product-ad quality test or cost comparison was performed. Panelly has not integrated 2.6, so its current model selector must not be presented as a way to execute this experiment.
Pick one decision the comparison must support
Suppose a fictional shop wants a static four-panel ad for a cream lunch box called MESA. It supplies an authorized product photograph and the exact line “MESA lunch box.” The decision is which model more often delivers an acceptable ad under one fixed request, not which has the more attractive single sample.
Separate a new composition from a label correction and a GIF loop. They exercise different tasks and should not be merged into one score. For the static composition, define acceptance around product identity, exact approved wording, reading order and a supported next action. Do not add sales conversion as an image-only metric.
Freeze settings before changing the model
Use the exact IDs in the official Flare and Sunburst pages. Both document generation and editing; neither page publishes a task-specific winner for your shop.
Keep the same input files, their order, prompt, operation, output dimensions, quality and complexity. Decide how to count blocked, failed or timed-out attempts before running. If you optimize a different prompt for each model, label that as a different comparison rather than quietly treating it as the controlled one. Equal token rates do not establish equal final cost: compare actual usage if an authorized experiment is later run.
Put the idea to work for your product
Four-panel product ads
Turn a product benefit into a connected four-panel ad. Explore a visual direction, refine the result through conversation, and download the complete image.
Try this in Panelly Edit the brief and replace the reference in Studio. Sign in when you are ready to create.Use a fixed original product-ad request
This illustrative prompt was not sent:
Create one complete static 2×2 four-panel product ad for the fictional cream MESA lunch box using the authorized product reference. Establish a quiet desk lunch setting, introduce the same box, show its visible shape and close with “Explore MESA”. Use the exact approved line “MESA lunch box”. Keep the product variant consistent. Do not add a price, insulation claim, leakproof claim, extra accessory or endorsement. Leave enough room to inspect and correct the wording.Replace the fictional identity before real use. The intended four positions are parts of one image, not a promise of separate editable files. Keep a copy of the request and input hashes so an attractive later revision cannot replace the original experimental record.
Score acceptance and effort without inventing a winner
| Record | What it answers |
|---|---|
| Exact text and product identity | Is the result usable under the supplied brief? |
| Whole-image inspection | Did a local success hide a changed panel or invented claim? |
| Attempts and failures | How many accepted results came from all submitted jobs? |
| Actual elapsed time and usage | What did that sample cost in time and metered work? |
| Reviewer decision and correction count | How much review or repair was required? |
Use the same reviewers and rubric, blind model names where practical, and retain all outputs. Report counts with denominators rather than rounding one successful generation into 100 percent. A small test remains uncertain even when one model wins its sample. Do not turn a model card's wording into an independently verified speed claim, or a quality score into an advertising conversion forecast.
Keep current Studio work separate from the future experiment
Prepare approved facts in the Brief builder and use the four-panel Studio task for a current static-ad workflow. Its visible model choice and displayed cost govern that actual task. We have not used it to generate any of the fictional MESA outputs described here.
For an existing result, feedback examples help state a repair precisely; compare the whole next version. The useful next step is to define an acceptance rubric and freeze a request before spending on a model test. An honest comparison can conclude “not enough evidence yet”; it should not invent a winner to make an article sound decisive.